LIVE Data Engineering Bootcamp for Analysts: Become the End-to-End Data Professional
From Data Analyst to Data Engineer in 11 Weeks.
Cohort 3 · Starts Saturday, 31st Oct, 2026. Inner Circle pricing until Tuesday, 10th November. Move from data analyst to data engineer through Codebasics' live 11-week cohort for working professionals. Learn warehouse-grade SQL, production Python, PySpark, Delta Lake, Azure, Microsoft Fabric, dbt, Airflow, CI/CD and streaming while building and shipping one end-to-end pipeline. Classes run live every Saturday and Sunday, 5 to 8 PM IST, with doubt clearing in every session and recordings for revision. The Diwali weekend, 7th and 8th November, is a planned break.
11
Weeks
20
Live Sessions
10+
Tools & Platforms
8
Capstone Layers
1 Year
Access to Class Recordings
27+
Enrolled Learners

Join a cohort of working data analysts
Build production pipelines, SQL to streaming
Ship one pipeline repo you can walk any interviewer through
Codebasics Promise
We stand by the quality of our content. Not satisfied? Get a full refund, no questions asked, until the day after your first 2 live sessions after enrolling.
Added Benefit
If you have already taken our paid Data Engineering course(s) or bootcamp, you will pay only the difference (This Bootcamp Price - Money You Paid for Data Engineering course(s) or bootcamp Price)
11
Weeks
20
Live Sessions
10+
Tools & Platforms
8
Capstone Layers
1 Year
Access to Class Recordings
27+
Enrolled Learners
Our Promise: in 11 weeks, this is who you become
-
Today you pull data someone else prepared. Week 11: you build the pipeline that prepares it.
-
Today your SQL answers one question. Week 11: you write MERGE, incremental loads and CDC that keep a warehouse current.
-
Today Spark and Databricks are lines on a job post. Week 11: you tune a Spark job by reading the Spark UI.
-
Today your report breaks when a source changes. Week 11: your pipeline is tested, scheduled, and tells you first.
-
Today you hand requirements to engineering. Week 11: you design the lakehouse on Azure and Fabric and defend the trade-offs.
Busy with the festive season? We’ve got you covered.
Classes before Diwali: 31st Oct and 1st Nov. Missed any? They’re all recorded.
Unlock instantly. Watch them during the festive week.
An instructor recaps sessions 1 and 2 and takes your questions.
Same capstone, same instructors, same final demo.
Overview
What you'll learn in
this Live Data Engineering for Data Analyst Bootcamp
Week-1: SQL for Modern Data Engineering
Phase 01 · Foundations
-
Session 1 - SQL for Modern Data Engineering - Part 1
Joins beyond INNER & OUTER · join algorithms (nested loop · hash · merge) · anti-joins · window functions deep dive · partition/order/frame · ranking & running totals
Output: A ranking and running totals query pack on a sample warehouse
-
Session 2 - SQL for Modern Data Engineering - Part 2
Recursive CTEs · MERGE statements · incremental loading patterns · CDC concepts · query execution plans · warehouse optimisation
Output: An incremental load built with MERGE and tuned from the execution plan
Week-2: Festival Break
Break · No new content
-
Festival Break: Diwali
No sessions. Diwali weekend
Week-3: Data Modelling and Production Python
Phase 01 · Foundations
-
Session 3 - Data Modelling & Warehouse Engineering
OLTP vs OLAP · star & snowflake schema · fact vs dimension tables · SCD Type 1 & 2 · partitioning strategies · medallion architecture · data contracts
Output: A dimensional model with SCDs on a Bronze, Silver, Gold layout
-
Session 4 - Production Python for Data Engineers
Modular Python architecture · OOP for pipelines · config-driven frameworks · logging & exception handling · retry mechanisms · environment management · secrets handling
Output: A config-driven Python pipeline framework with logging and retries
Week-4: Advanced Python and PySpark
Phase 01 · Foundations
-
Session 5 - Advanced Python Data Processing
APIs & ingestion patterns · async processing · parallel execution · file streaming · memory optimisation · testing with pytest · packaging basics
Output: A tested async ingestion job that streams large files without blowing memory
-
Session 6 - PySpark Deep Dive
Spark architecture · executors & DAGs · lazy evaluation · partitioning · broadcast joins · shuffle optimisation · Spark UI analysis · caching strategies
Output: A Spark job you have tuned yourself using the Spark UI
Week-5: Stakeholders and Career Guidance
Phase 01 · Foundations
-
Session 7 - Stakeholder Management + Personal Branding
Stakeholder communication · framing requirements · explaining technical work to non-technical audiences · personal branding · building online credibility as a data engineer
Output: A stakeholder update on your own work and a LinkedIn profile that reads like a data engineer's
-
Session 8 - Career Guidance (Open Q&A)
Open career question and answer. Where you are now and where data engineering fits · choosing a direction · moving into engineering inside your current company versus switching · career gaps and transferable skills · realistic timelines · what to do when applications go quiet · and whatever else learners bring
Output: Your own career question answered, with one concrete next step written down
Week-6: Delta Lake and the Azure Stack
Phase 02 · Platforms & Cloud
-
Session 9 - Delta Lake & Lakehouse Engineering
Delta internals · ACID transactions · OPTIMIZE & ZORDER · time travel · schema evolution · Change Data Feed · incremental ETL · Bronze/Silver/Gold
Output: An incremental ETL pipeline running on Delta Lake
-
Session 10 - Azure Data Engineering Stack
ADLS Gen2 · Event Hubs · Key Vault · managed identities · Integration Runtime · networking basics · Synapse vs Databricks vs Fabric
Output: A secured Azure data landing zone using Key Vault and managed identities
Week-7: Enterprise Pipelines and Microsoft Fabric
Phase 02 · Platforms & Cloud
-
Session 11 - Enterprise Data Pipelines
Azure Data Factory · Fabric Pipelines · Databricks Workflows · metadata-driven pipelines · config-based orchestration · parameterisation · reusable frameworks
Output: A metadata-driven, parameterised orchestration pipeline
-
Session 12 - Microsoft Fabric Engineering
OneLake · Lakehouse & Warehouse · Fabric Data Factory · Eventstream · Real-Time Intelligence · DirectLake · Fabric governance
Output: An end-to-end Fabric solution with DirectLake reporting on top
Week-8: dbt and Connecting the Dots
Phase 03 · Transformation & Orchestration
-
Session 13 - dbt Core Fundamentals
Models & sources · refs() · materialisations · snapshots · incremental models · tests · documentation
Output: A tested, documented dbt project with incremental models and snapshots
-
Session 14 - Connecting the Dots + Capstone Introduction
End-to-end view of the stack so far · how the pieces fit · architecture recap · trade-offs between platform options · concept clarity & doubt clearing · capstone brief & assessment criteria
Output: One architecture diagram of the full stack, explained in your own words, plus your capstone brief
Week-9: Airflow and CI/CD
Phase 04 · Production & Launch
-
Session 15 - Apache Airflow Engineering
Airflow mental model · DAGs · tasks & operators · TaskFlow API · anatomy of a DAG file · scheduler & executor · start_date · schedule intervals & catchup · XCom · retries & alerting · connections for secrets · monitoring · top-level code traps
Output: Scheduled Airflow DAGs that retry, alert and survive failures
-
Session 16 - CI/CD & Reliability Engineering
Git branching strategies · GitHub Actions · automated testing · deployment pipelines · monitoring & freshness checks · cost optimisation · incident management
Output: A CI/CD workflow with automated tests and freshness checks
Week-10: Streaming, Interviews and Capstone Jamming
Phase 04 · Production & Launch
-
Session 17 - Streaming Data Engineering
Kafka fundamentals · event-driven architecture · Structured Streaming · watermarking & windowing · event-time processing · CDC streaming · Event Hub integration. Capstone work continues alongside
Output: A streaming pipeline that handles late-arriving data with watermarks
-
Session 18 - Winning Data Engineering Interviews
The reframe (depth beats tricks) · your resume as the question paper · the intersection framework · thinking like the client · answering like a senior · the non-negotiables they always test (SQL & data modelling) · reverse interviewing · multi-round strategy · using AI as a sparring partner · handling what you do not know · the 7-day prep playbook
Output: A seven day interview prep plan built from your own resume
-
Session 19 - Capstone Jamming Session (midweek, 7:30 to 9:00 PM IST)
Implementation questions on the capstone · design review · debugging together · unblocking pipeline issues · peer feedback
Output: Your capstone unblocked, with a clear next step
Capstone Build Week
Capstone Build Week
-
No Cohort 3 session. Capstone build time
No sessions, time to finish, test and document your capstone.
Week-11: Capstone Build and Graduation
Phase 04 · Production & Launch
-
Session 20 - Final Demo + Graduation (evening, 8:00 to 9:30 PM IST)
Capstone demo covering data ingestion · lakehouse architecture · PySpark transformations · dbt modelling · Airflow orchestration · CI/CD · Power BI reporting and the monitoring layer
Output: One production-grade pipeline repo covering all eight layers, ready for a hiring manager to read in five minutes
Learn From
Your Instructors
Dhaval Patel
Founder, Codebasics · Ex-NVIDIA
Curriculum advisor. Sets what this cohort teaches and what it refuses to.
I have 17 years of experience in programming and data science at leading tech companies like NVIDIA and Bloomberg. I also run Codebasics, a leading YouTube channel for data science, ML, and data structures. I believe "anyone can code", so I use analogies, simple explanations, and step-by-step storytelling to make complex concepts easy to understand, even for high school students.
Hemanand Vadivel
Co-Founder & CEO, Codebasics
Leads most sessions and every leadership and management block.
I was among the top 1% with my amazing data analytics job in the UK. I left the job to stay back in India and pursue something that gives me a better sense of being and more joy - creating a positive impact on society by sharing knowledge.
Kirandeep Marala
Analytics Engineer and Programme Manager, Codebasics
Plans every session, builds the assignments, and evaluates what you ship.
I started in analytics four years ago, answering business questions with SQL and dashboards, until the pipelines underneath pulled me into engineering. Now I manage the Data Engineering Bootcamp: I plan sessions with Harun, build assignments and notes, and evaluate what you ship. Every case is fresh, because I want transfer, not recall.
Harun Raseed
Lead Data Engineer, Hitachi Solutions
Leads every technical session, from SQL execution plans to Kafka. Whiteboard first, code second, then stays for doubts.
I lead a data engineering team building enterprise platforms on Azure and Databricks. Ten years taught me the hard part is not the code, it is knowing what the engine did with it. So I teach whiteboard first, then code, then the execution plan. I am a Microsoft Certified Trainer and Databricks Certified Professional. You will read pipelines like I do.
The Stack
Tools You'll Work With

ADLS Gen2 + Key Vault
Storage and secrets
Apache Airflow
Scheduling
Apache Kafka
Streaming
Azure Data Factory
Orchestration
Azure Event Hubs
Event ingestion
Databricks
Lakehouse platform
dbt Core
Transformation
Delta Lake
ACID tables
Docker
Local environments
GitHub Actions
CI/CD
Microsoft Fabric
Lakehouse and pipelines
Power BI · Reporting
Reports and verified DAX
PySpark
Distributed processing
Pytest
Testing
Python
The language of every build
SQL Server
Warehouse SQLHear It From
Our Happy Learners
Our content is rated 4.9/5 from 18631+ Learners
 Python

 SQL


Some things arrive at exactly the right moment. Codebasics launching its live cohorts was one of them for me, landing just as I set out to become a full-stack data professional. My story with Codebasics actually began with their Power BI course, which quietly shaped everything I do today, so I walked into the Data Engineering for Data Analysts cohort with high expectations. It is exceeding them, session after session.
Haroon teaches like a practitioner, not a lecturer. He shows us what data engineers really do in production, the messy, decision-heavy reality rather than tidy textbook examples. Every session is three focused hours of pure signal, no filler. So far we have journeyed through modern SQL (window analytics, recursive CTEs, MERGE-based change loading, execution-plan tuning), dimensional modeling and warehouse engineering (star schemas, SCD Type 2, partitioning), production and advanced Python, PySpark on Databricks, Delta Lake and lakehouse engineering, and orchestration with Azure Data Factory, with a few sessions still ahead. The assignments feel handcrafted; each one snaps neatly onto the classwork and cements it. And the capstone project is a genuine gem, pulling the entire curriculum into one realistic, end-to-end challenge.
Behind the scenes, Kirandeep runs the cohort with a care and precision that makes everything feel effortless for the participants. I am equally grateful to Dhaval Patel and Hemanand Vadivel, the cofounders of Codebasics, who have been mentors and good friends, and whose vision set all of this in motion.
This cohort is steadily carrying me from the consumption layer up into the engineering layers I once only admired from below. If you are a BI or analytics professional serious about going full-stack, I recommend the Codebasics DE for DA bootcamp without a second thought. Thank you, Haroon, Kirandeep, Dhaval, Hemanand, and the entire Codebasics team.

 LIVE DE Bootcamp: Batch 1
Landed a Job
I really enjoyed the LIVE Data Engineering Bootcamp for Analysts. The best part of the course was definitely Harun. His depth of knowledge is incredible, and he doesn't just teach how things work, he explains why they work that way. That made it much easier to understand concepts that initially felt overwhelming.
Another thing I appreciated was the Codebasics team. During the live cohort, they were always available to answer questions, so the class didn't have to stop every few minutes for doubts. That kept the sessions running smoothly while making sure everyone's questions were answered.
One thing I realized during this cohort is that Data Engineering is not as easy as Data Analytics. As someone transitioning from a Tableau and Data Analytics background, I found that having a strong foundation in SQL and at least the basics of Python makes a huge difference. My suggestion to future learners is to complete the Codebasics Data Engineering Bootcamp first. If that's not possible, at least become comfortable with SQL and Python before joining the live cohort. Since each three hour class covers a major topic, the pace can feel fast if you are completely new to these technologies.
That said, the support system is excellent. We have recorded sessions, an active Discord community where learners help each other, and the instructors genuinely listen to feedback. There were times when many of us felt the pace was a little too fast, and the team actually slowed things down after listening to our feedback. That showed they genuinely care about helping students learn instead of just finishing the syllabus.
Overall, I had a great learning experience. The journey was challenging, but it was absolutely worth it. If you are serious about moving from Data Analytics to Data Engineering, I would definitely recommend this cohort. It gives you the right guidance, practical learning, and a supportive community to help you make that transition.

Landed a Job
With seven years in data engineering, I wanted to strengthen my fundamentals, learn modern DE technologies, and build interview confidence, ideally through a practical, production-focused crash course rather than a purely theoretical one. The CodeBasics Data Engineering Bootcamp matched that exactly, with its syllabus and focus on building a real, production-ready ETL pipeline.
Here's my genuine feedback.
Teaching Style: Concepts were taught with real context, why, where, and how they're used in production, not just theory.
Learning Material: The learning material is excellent and well organized. We received live session recordings, concise key notes, and detailed material, plus compiled Q&A from live chats, sample code for topic discussed with brief notes. Recoded sessions are also available technology wise.
Assignments: Designed around real-world scenarios, which made them especially valuable for interview prep.
Interview-Readiness Tracker: A standout feature, giving a clear checklist across topics like SQL and DE concepts, so I always knew what to revise and what was already covered.
Quizzes: Regular quizzes kept things engaging with healthy competition, and answer PDFs helped us pinpoint exactly where we went wrong.
Team Support: The instructor was patient and thorough, and both the instructor and support team made sure no question went unanswered.
Discord Community: A great space for ongoing discussions, technical questions, and connecting with fellow learners outside class.
Flexibility: The team genuinely listened to feedback after sessions and acted on it, the interview tracker itself was born from a suggestion.
Understanding: They extended the capstone submission timeline knowing everyone was balancing full-time jobs, and built in a week off between sessions to let us catch up and connect the dots, rather than just rushing through the syllabus.
Overall, this bootcamp delivered exactly what I needed: structured, practical, interview-focused learning that strengthened my fundamentals and boosted my confidence for both real-world projects and interviews. I'd highly recommend it to anyone looking to upskill in data engineering.
Special thanks to Harun and Kiran for their support throughout the course, to Hem and Varun for the stakeholder management, personal branding and interview-specific sessions, and to Dhaval for building such an excellent platform for real-time learning.

An Excellent Journey into Modern Data Engineering
The AI Data Engineering Bootcamp has been an excellent and highly practical learning experience. It covered everything from SQL, Python, data modelling and warehousing to PySpark, Delta Lake, Lakehouse, Azure Data Factory, Microsoft Fabric, dbt, CI/CD and end-to-end data engineering.
The progression from fundamentals to real-world engineering practices made the learning journey both structured and impactful.
A special shoutout to Harun, who was an outstanding instructor. His ability to simplify complex concepts, patiently address questions, and ensure everyone understood before moving forward made a huge difference.
And a big thank you to Kiran from Codebasics team for the incredible coordination throughout the cohort. Managing a diverse group of learners, coordinating with the management team, resolving questions promptly, and keeping everything running smoothly was truly commendable.
Overall, a fantastic experience that has strengthened my data engineering skills and given me greater confidence to work with modern data platforms. Highly recommended!
The Codebasics Cohort Training on DA to DE has Surpassed my Expectation. I Would like to Mention few things here
Harun - Has Great Skills on Multiple Technologies and Great at Training ,
Kiran - As a back up or Leading the Chat and Providing all the related Content and looking after Issues was in Sync with the Cohort.
The Concepts Explanations and Real world Scenarios were on Point.
Although i had personal Commitments and could not attend sometime, Every Class is Recorded and uploaded in 24 hours which is great boon.
I Appreciate the Patience the Team had and hoping to Continue with them for other learnings also.
Thank you Soo much Codebasics Team.

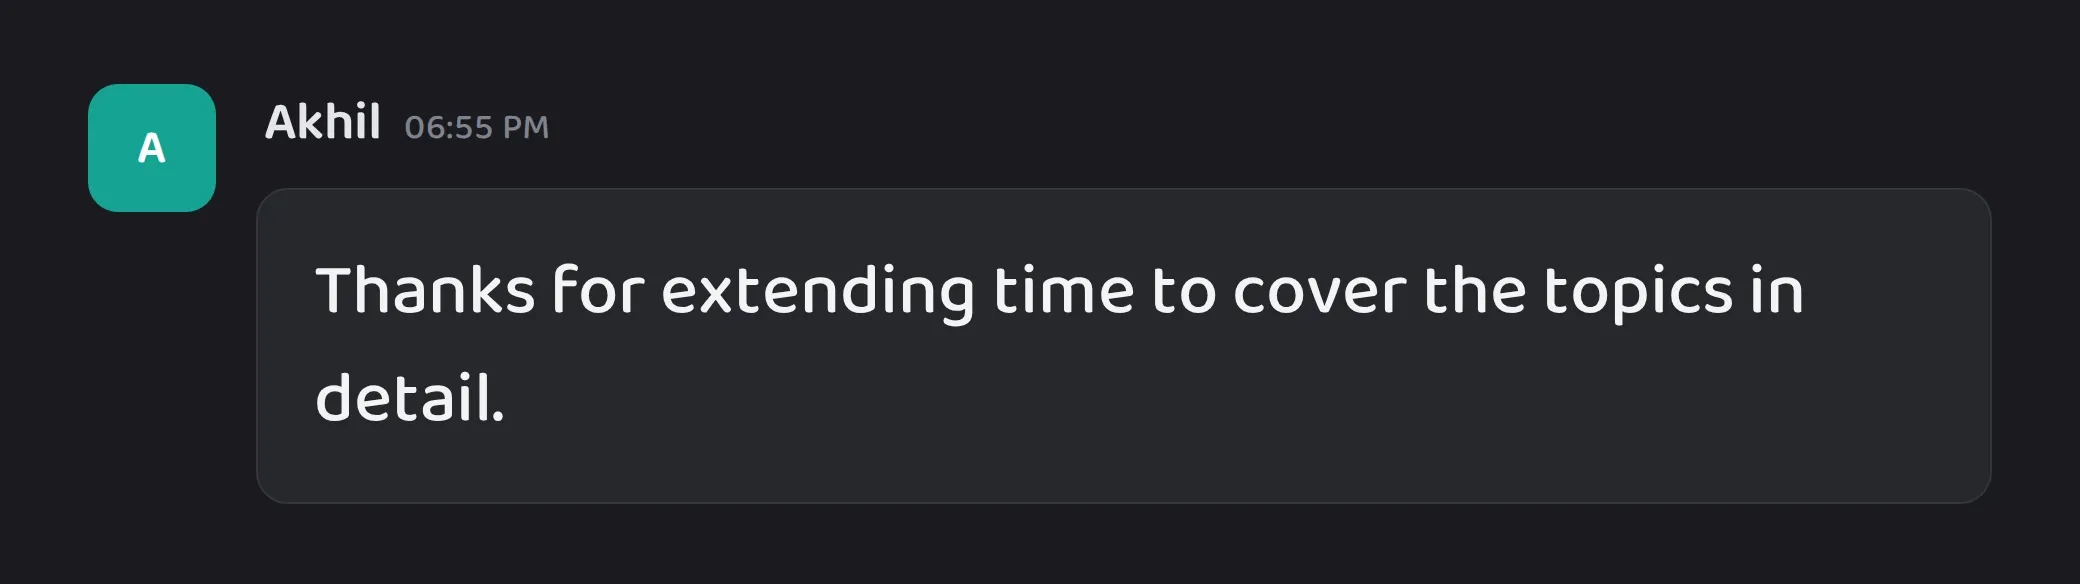
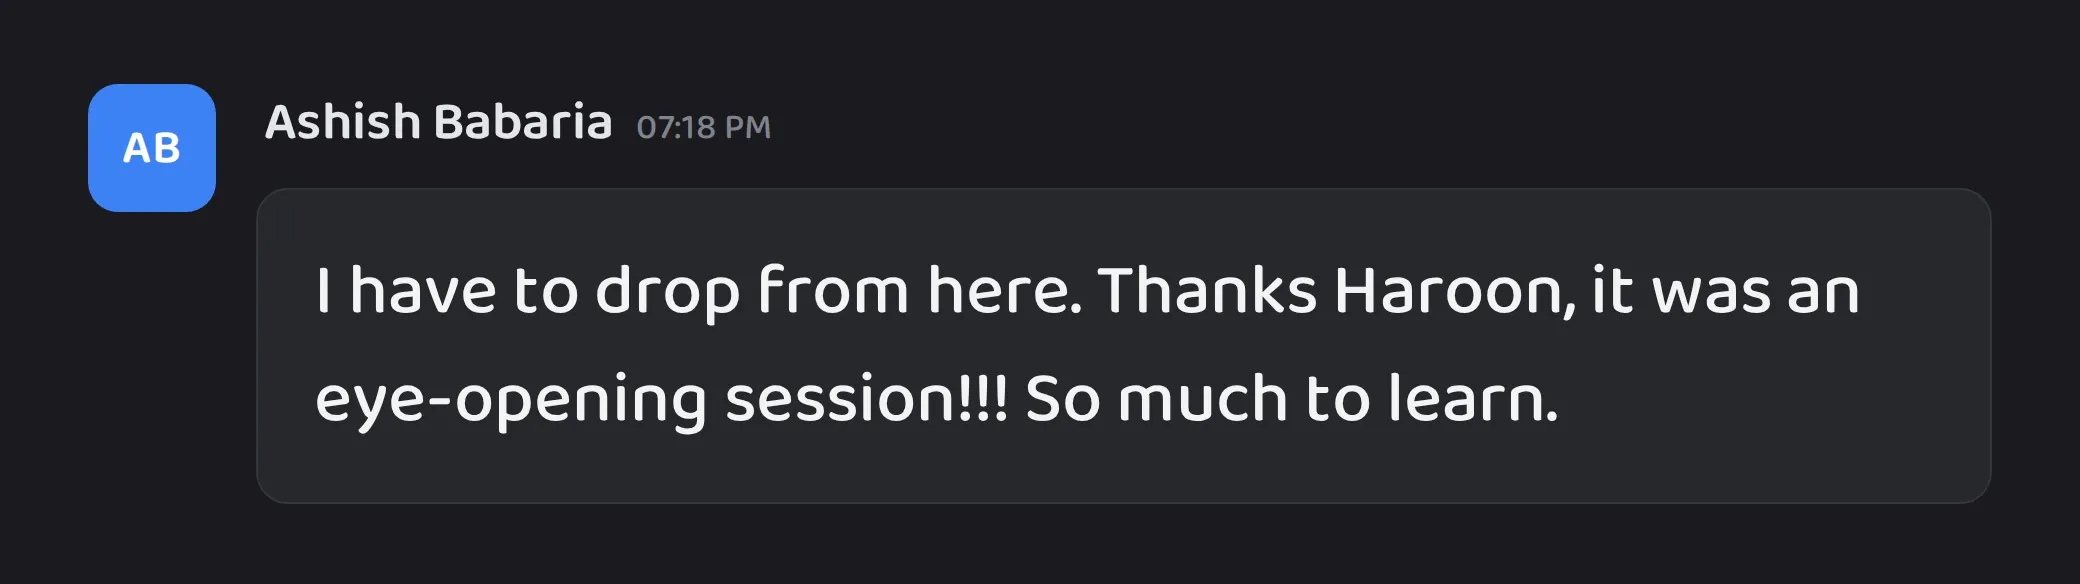
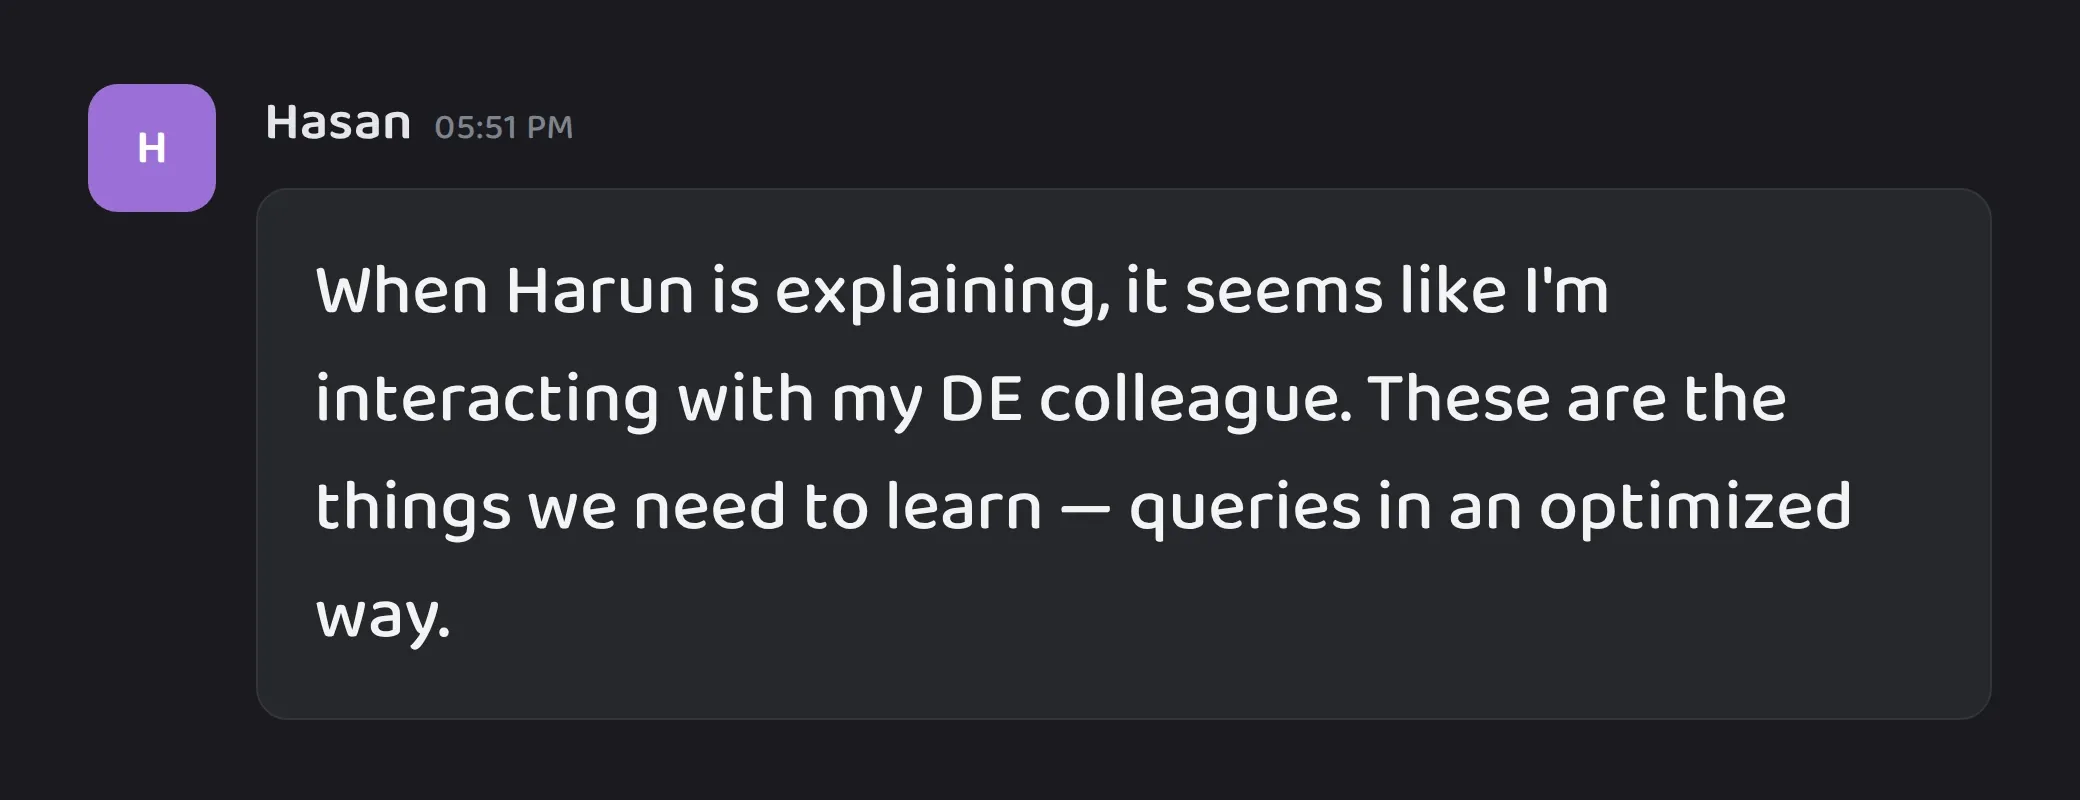
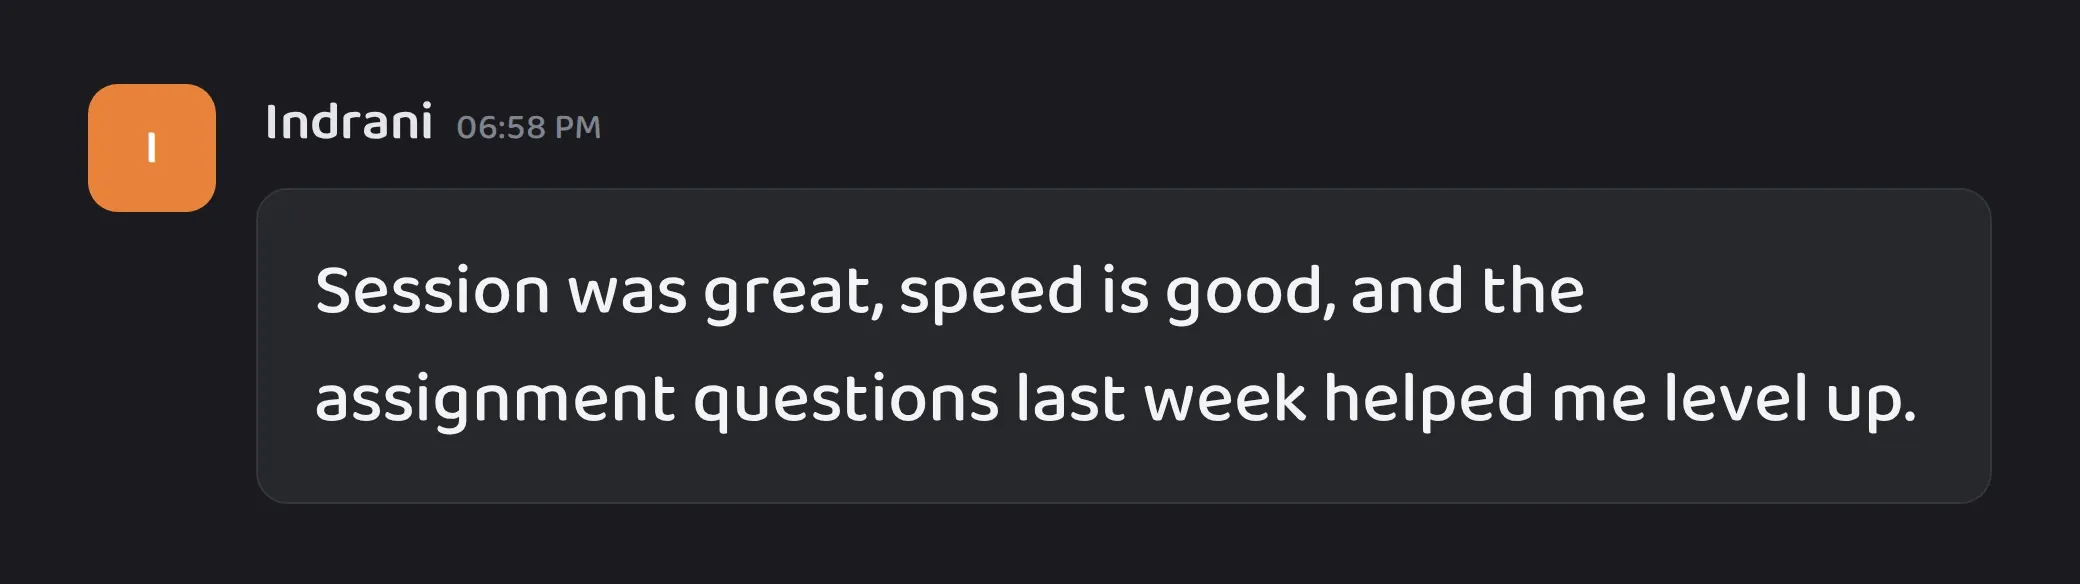
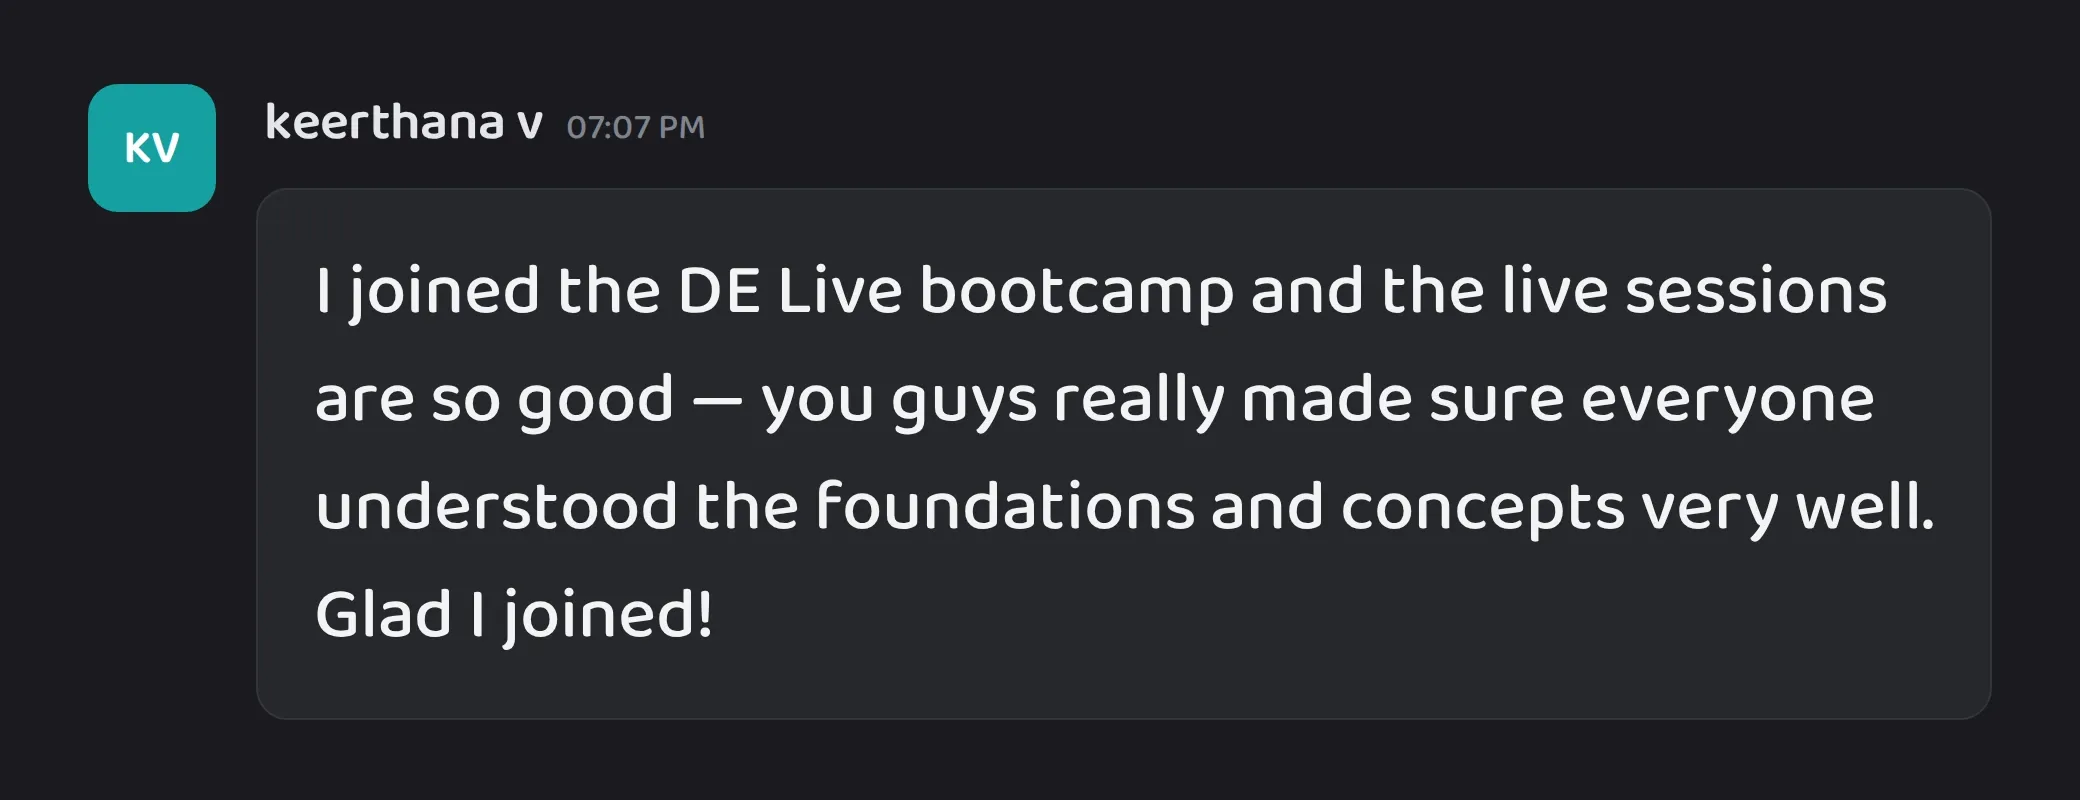
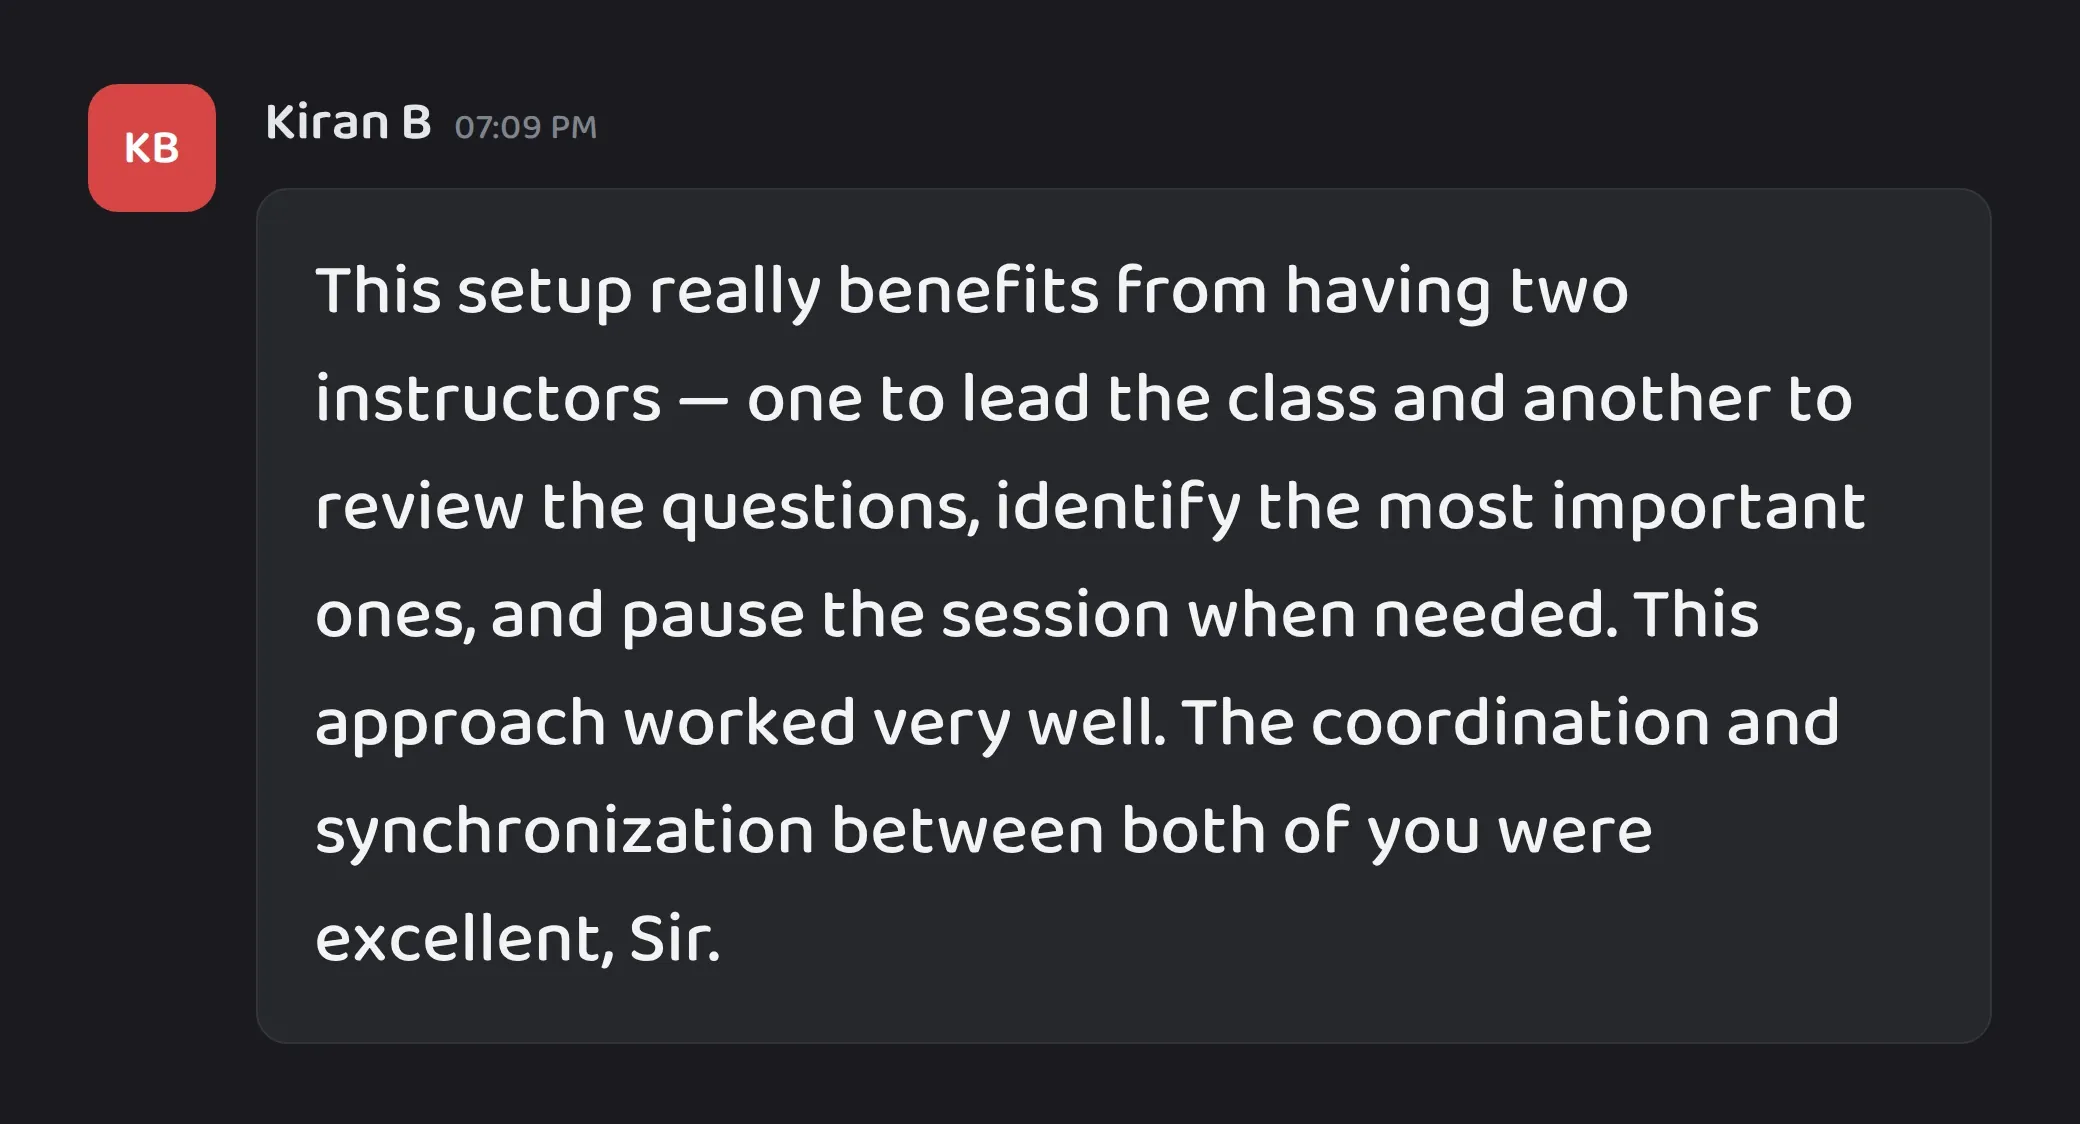
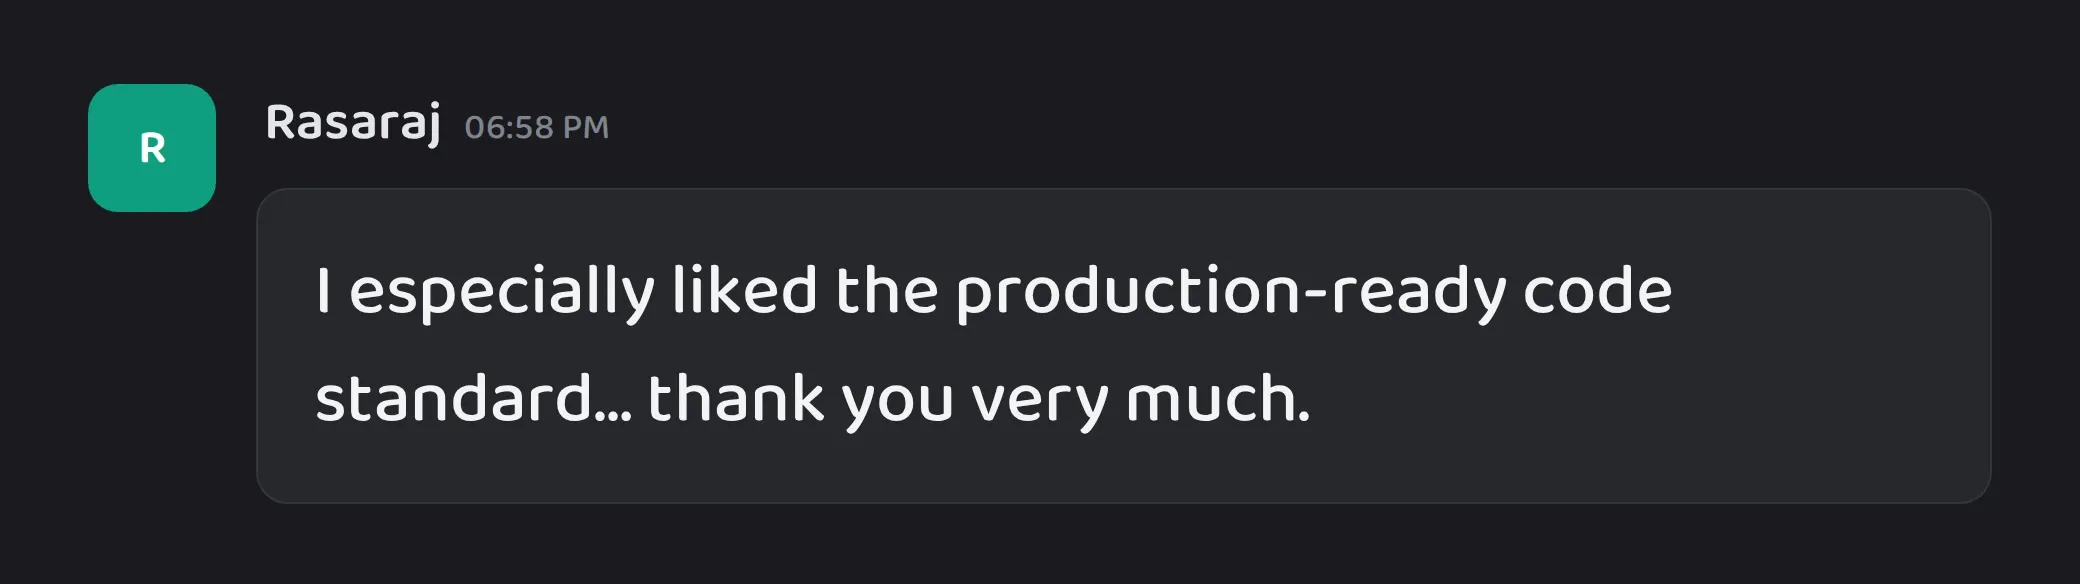
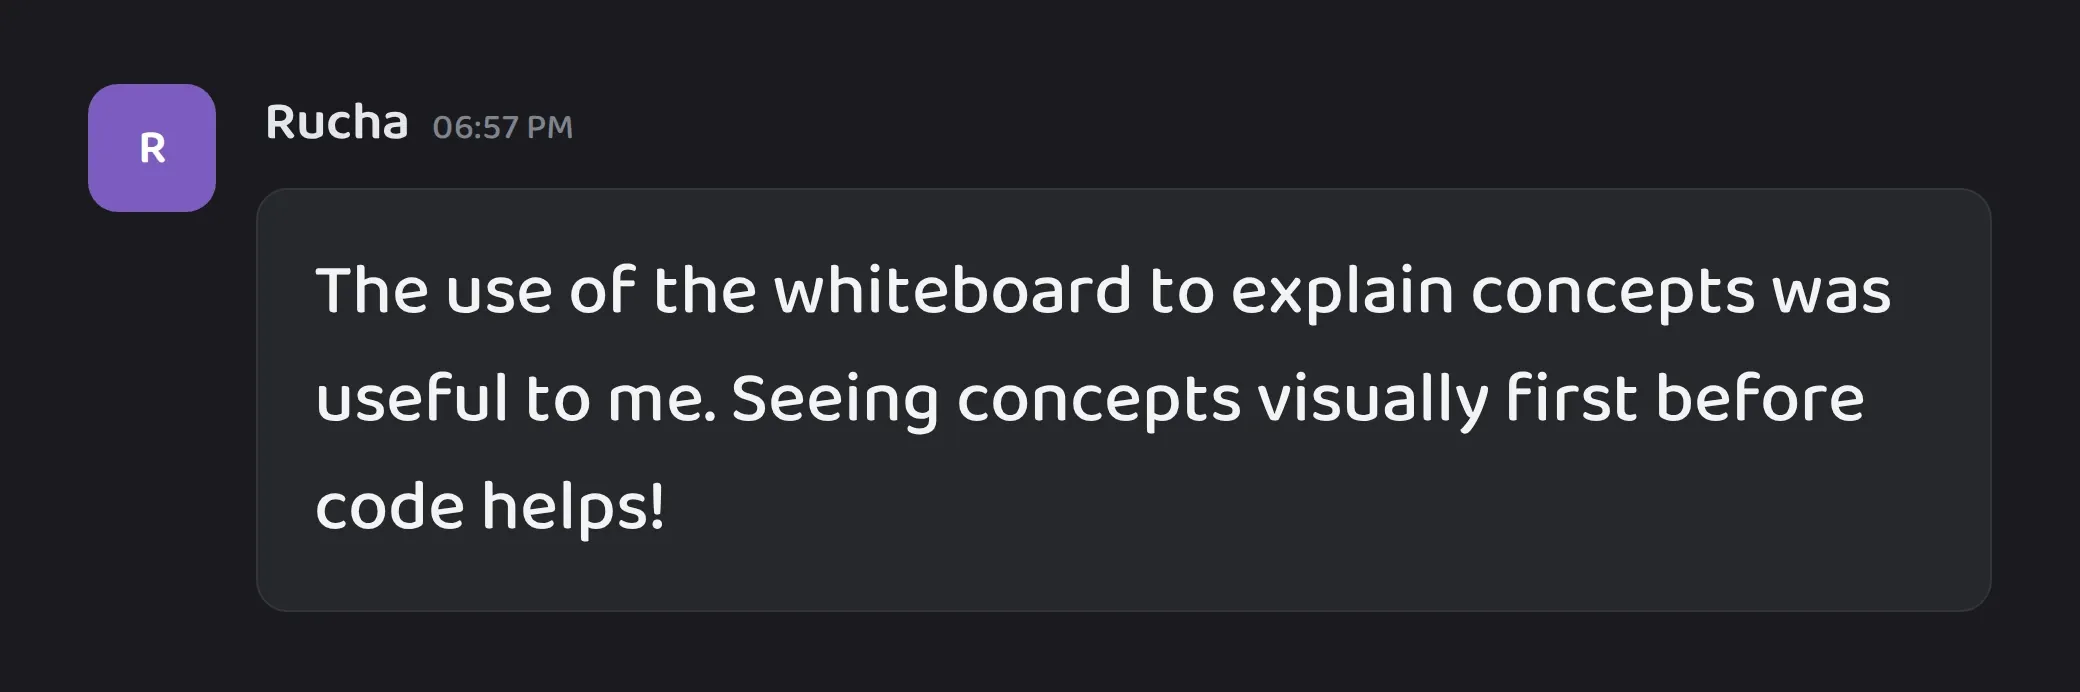
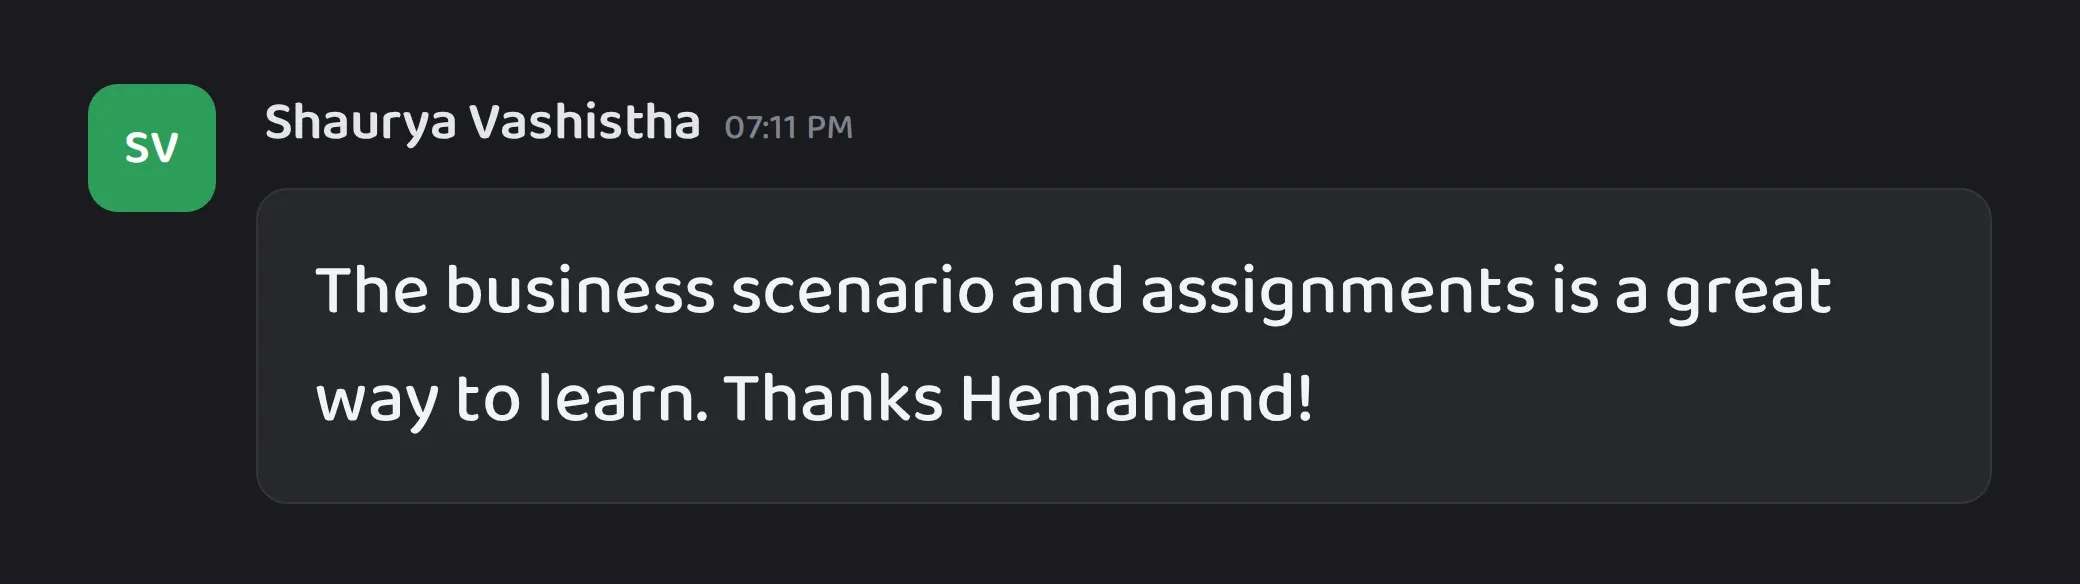
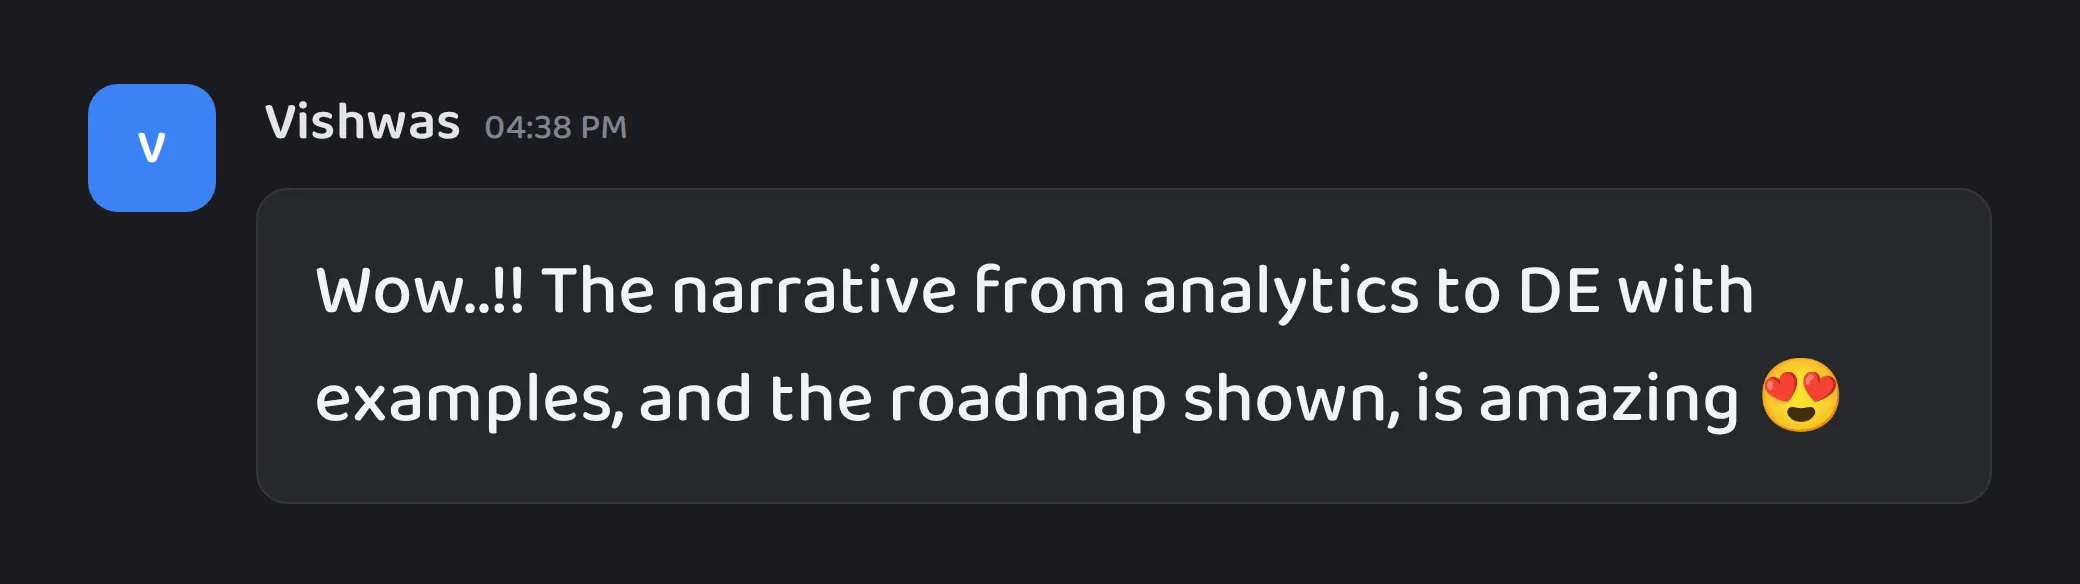
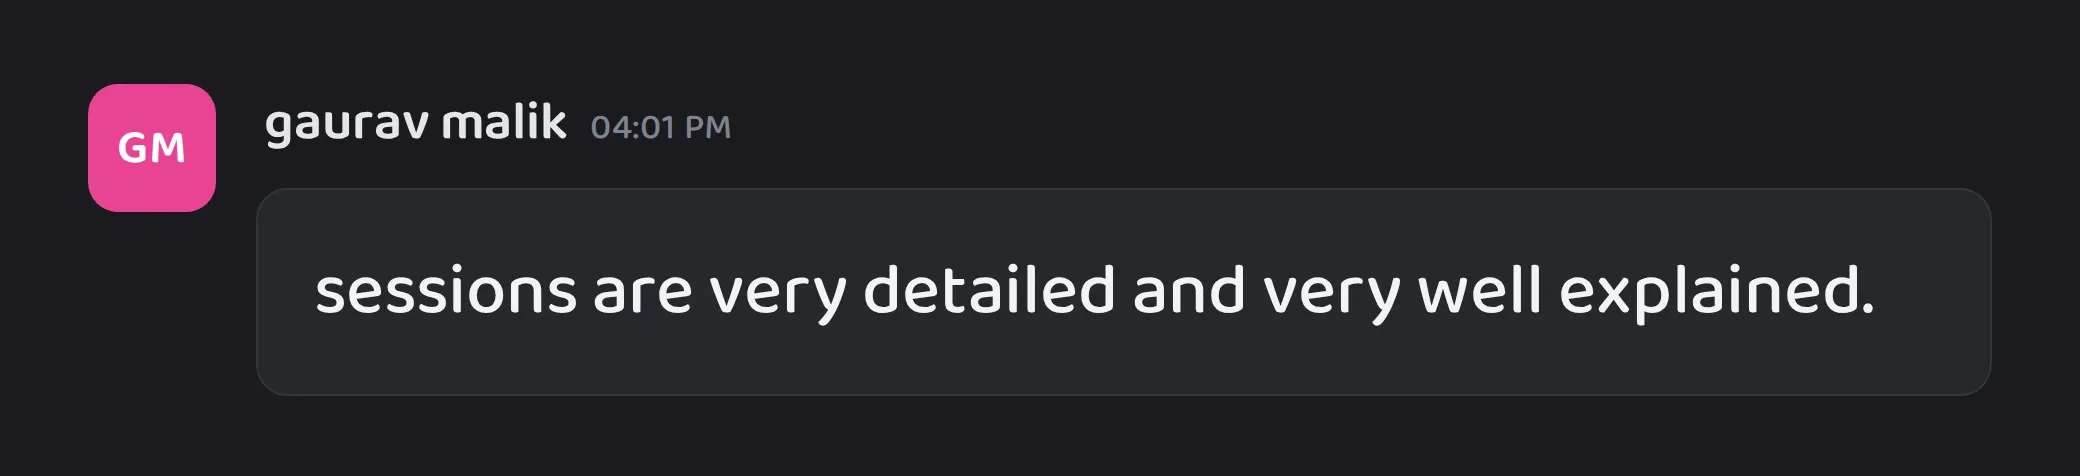
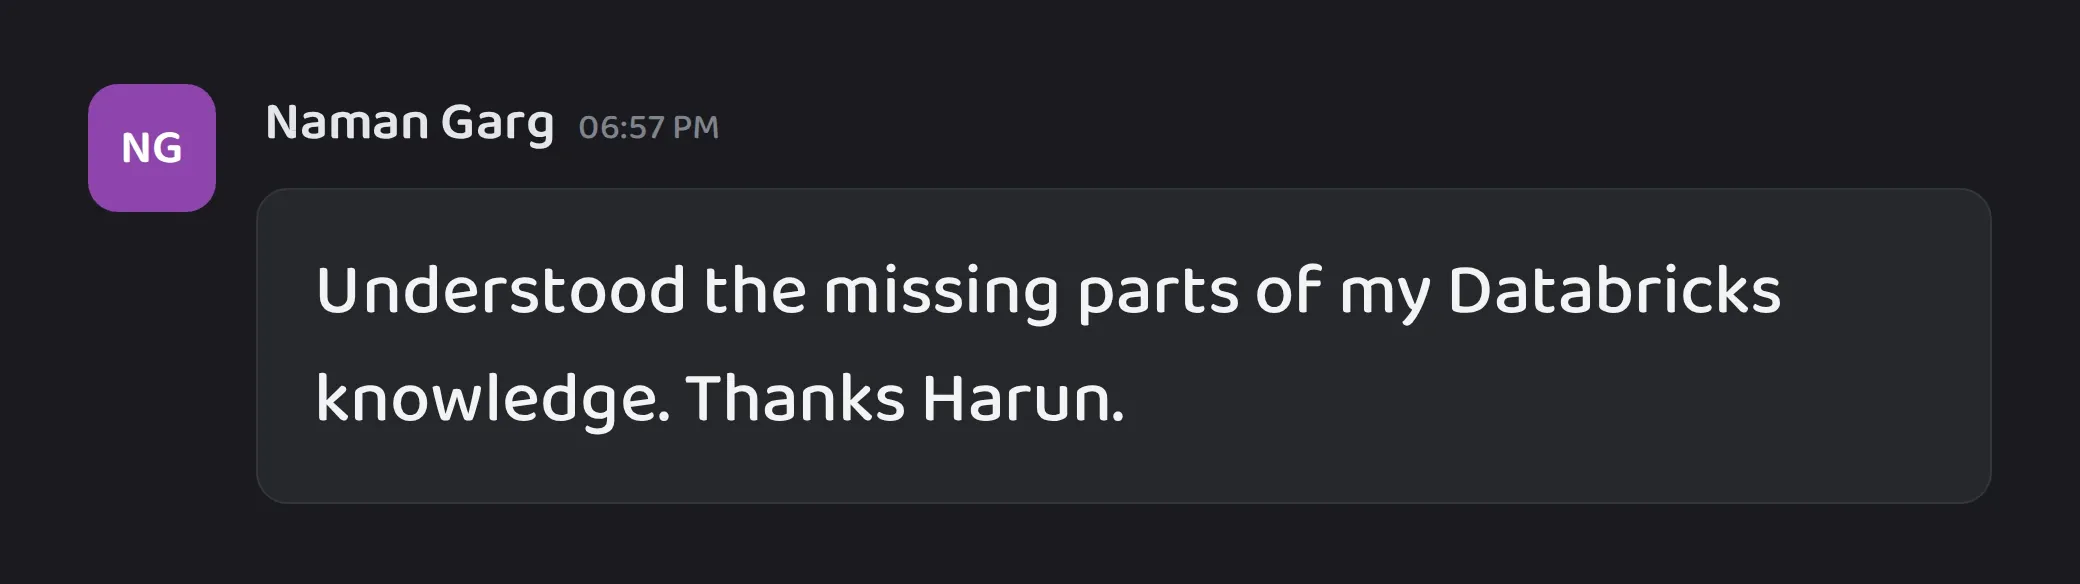
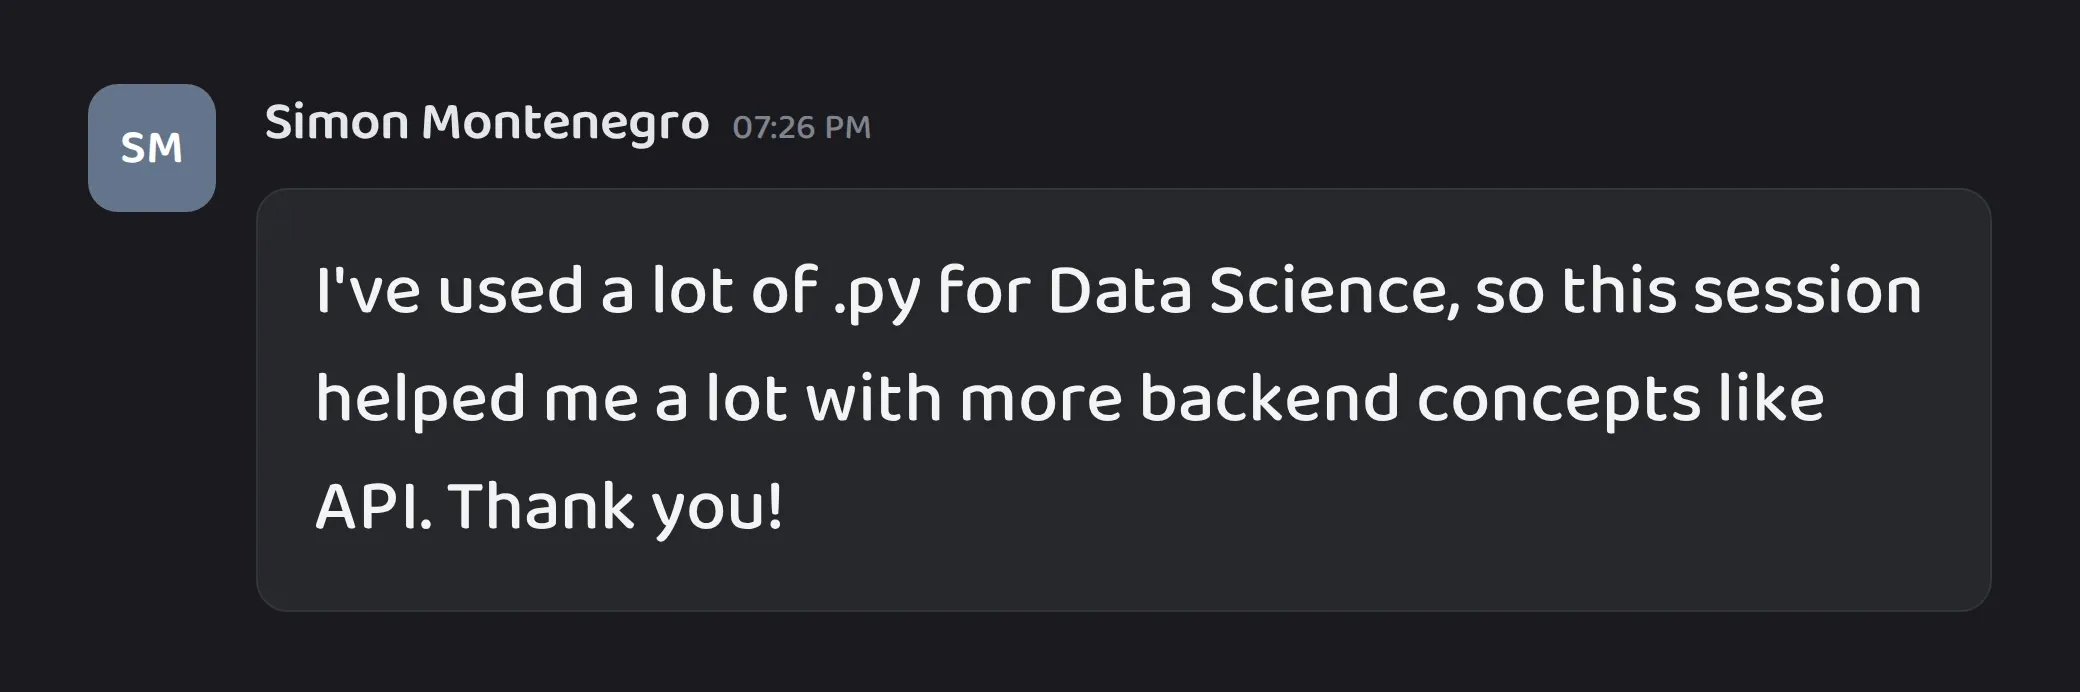
Straight from the live sessions
What Data Analysts typed in the cohort chat, unedited.
The Codebasics Promise
Build & Ship Production Data Pipelines in 11 Weeks.
Not a tutorial. A working end-to-end pipeline defended in front of mentors.
| What you get | Self-study | Other live bootcamps | Our live cohort |
|---|---|---|---|
| Live, mentor-led sessions | |||
| Real projects shipped to GitHub | Rarely | Sometimes | 1 pipeline repo |
| The current 2026 Cloud stack | On your own | Often outdated | |
| Investment | Your time | Usually far higher | US$630 |
May we help you?
Frequently Asked
Questions

Q.1
When does the bootcamp officially start?
Q.2
Do I also get the Data Engineering Bootcamp 1.0?
Q.3
What if I miss a live session?
Q.4
What happens after the 11 weeks? Do I lose access?
Q.5
What is Inner Circle, and how is it different from regular enrollment?
Q.6
Is there a break for Diwali?
Q.7
Which cloud do we use?
Q.8
What is the capstone?
Q.1
Do I need prior data engineering experience?
Q.2
I am a fresher with no work experience. Can I join?
Q.3
Who is this bootcamp designed for?
Q.4
Do I need to know Python or Spark already?
Q.1
How do I get help if I am stuck?
Q.2
Is there job assistance?
Q.3
Do you promise a job?
Q.1
I already own the Data Engineering Bootcamp 1.0. What do I pay?
Q.2
I bought only some individual courses from the Data Engineering Bootcamp 1.0. What do I pay?
Q.3
What is the investment, and is EMI available?
Q.1
I used a subsidy and now want to refund this Bootcamp itself. What happens?
Q.2
I used a subsidy (my existing Data Engineering Bootcamp or individual course purchase). Can I refund my original purchase after enrolling?
Q.3
What is the refund policy?
Please note: The refund window is based on the two live sessions scheduled after your enrollment, not on whether you attended them. If you miss a session, the refund window still moves forward.
To request a refund, email [email protected] before the window closes.
Please read the full refund policy here.
Q.1
When does the bootcamp officially start?
Q.2
Do I also get the Data Engineering Bootcamp 1.0?
Q.3
What if I miss a live session?
Q.4
What happens after the 11 weeks? Do I lose access?
Q.5
What is Inner Circle, and how is it different from regular enrollment?
Q.6
Is there a break for Diwali?
Q.7
Which cloud do we use?
Q.8
What is the capstone?
Q.1
Do I need prior data engineering experience?
Q.2
I am a fresher with no work experience. Can I join?
Q.3
Who is this bootcamp designed for?
Q.4
Do I need to know Python or Spark already?
Q.1
How do I get help if I am stuck?
Q.2
Is there job assistance?
Q.3
Do you promise a job?
Q.1
I already own the Data Engineering Bootcamp 1.0. What do I pay?
Q.2
I bought only some individual courses from the Data Engineering Bootcamp 1.0. What do I pay?
Q.3
What is the investment, and is EMI available?
Q.1
I used a subsidy and now want to refund this Bootcamp itself. What happens?
Q.2
I used a subsidy (my existing Data Engineering Bootcamp or individual course purchase). Can I refund my original purchase after enrolling?
Q.3
What is the refund policy?
Please note: The refund window is based on the two live sessions scheduled after your enrollment, not on whether you attended them. If you miss a session, the refund window still moves forward.
To request a refund, email [email protected] before the window closes.
Please read the full refund policy here.
Festive season? Catch up after Diwali. Inner circle US$630 extended to Tue, 10th Nov. Save ₹12,000.


